
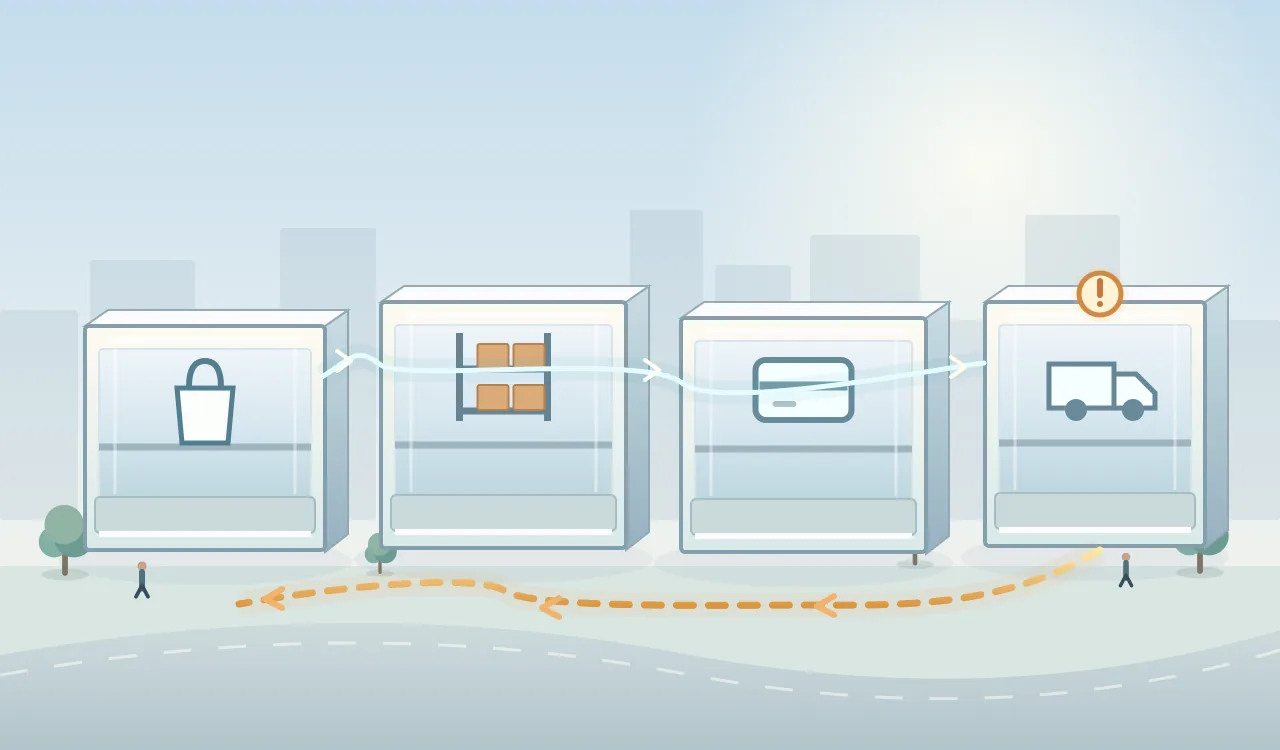
The customer has paid, inventory has been reserved, but delivery cannot be arranged. To the customer, this was one action: place an order. Behind the scenes, several independent systems have already committed changes, and there is no universal Undo button.
This is the problem Saga addresses. It coordinates one business process across services while making failure and recovery part of the design, rather than an unexpected conversation between the support team and the developers.
Why the usual rollback no longer works
Within a single database transaction, some changes can be committed together or rolled back together. That is a useful guarantee, but it only covers work that actually belongs to the transaction.
When orders, inventory, payments and shipping maintain their own data, each service can finish its work before the next one fails. The warehouse has reserved the item. Payment has been captured. The carrier is unreachable. The first two steps cannot simply pretend nothing happened.
A Saga breaks the business flow into local transactions and coordinates their outcomes. If a later step fails, it triggers compensating operations for steps already completed. Those operations must be designed and implemented explicitly.
A refund is a new transaction
Consider a reserved item and a captured payment followed by a delivery failure. The system may release the stock and initiate a refund. But the money might not be visible to the customer immediately. A refund has its own timeline and failure modes.
If payment was only authorised, releasing the authorisation may be the right response instead. That is different from refunding captured funds. A workflow diagram can make both look like a backwards arrow; the business cannot afford to treat them as identical.
Some operations cannot be reversed in any meaningful sense. An email has been read, a parcel handed to a carrier, or an external provider has started work. Compensation may reduce the damage, but it does not put time back in the bottle.
That makes the order of operations important. Where possible, keep irreversible steps until the necessary checks and reservations have succeeded.
Who owns the order in the middle?
The hardest failure is often an ambiguous one. The payment request times out. Did the money move, or did only the response get lost? Retrying blindly can turn a delayed payment into a duplicate charge.
The workflow therefore needs durable state, safe retries, handling for repeated messages and a way to resume after a crash. Idempotency and reliable event publication matter because real distributed systems repeat messages and lose responses.
Yet a technical recovery mechanism is not a business owner. If a refund fails, who is alerted? Who tells the customer what is happening? At what point does an operation move to manual handling? A company can distribute implementation. It still needs clear ownership of the whole customer journey.
One conductor, or services reacting to each other?
Sagas commonly use orchestration or choreography. With orchestration, a coordinator records progress and tells participating services what comes next. This makes long or exception-heavy workflows easier to inspect, although the coordinator itself must be operated reliably.
With choreography, services publish events and react to one another. There is no central controller, but as the flow grows, following an order across teams and messages can become surprisingly difficult.
I would not choose choreography merely because it sounds more distributed. A complex flow with timeouts, refunds and human intervention often benefits from an explicit owner and a visible process state.
And neither approach automatically restores database-style isolation. Two orders may still compete for the same stock while their sagas are progressing. Concurrency rules and reservations remain separate design problems.
When a Saga is unnecessary
If the whole operation can safely stay in one local transaction, a distributed workflow adds costs without necessarily solving a problem. Retries, compensation and message delivery are not improvements on their own.
A Saga becomes relevant when separate systems are justified for other reasons and a business operation must cross their boundaries. Before approving one, I would ask for three walkthroughs alongside the happy path: a failed step, an unknown outcome and a failed compensation.
The value is not that Saga magically turns several systems into one transaction. It forces the company to decide what happens to work and money when a process stops halfway.
For the underlying mechanics and limitations, see the Saga pattern reference.